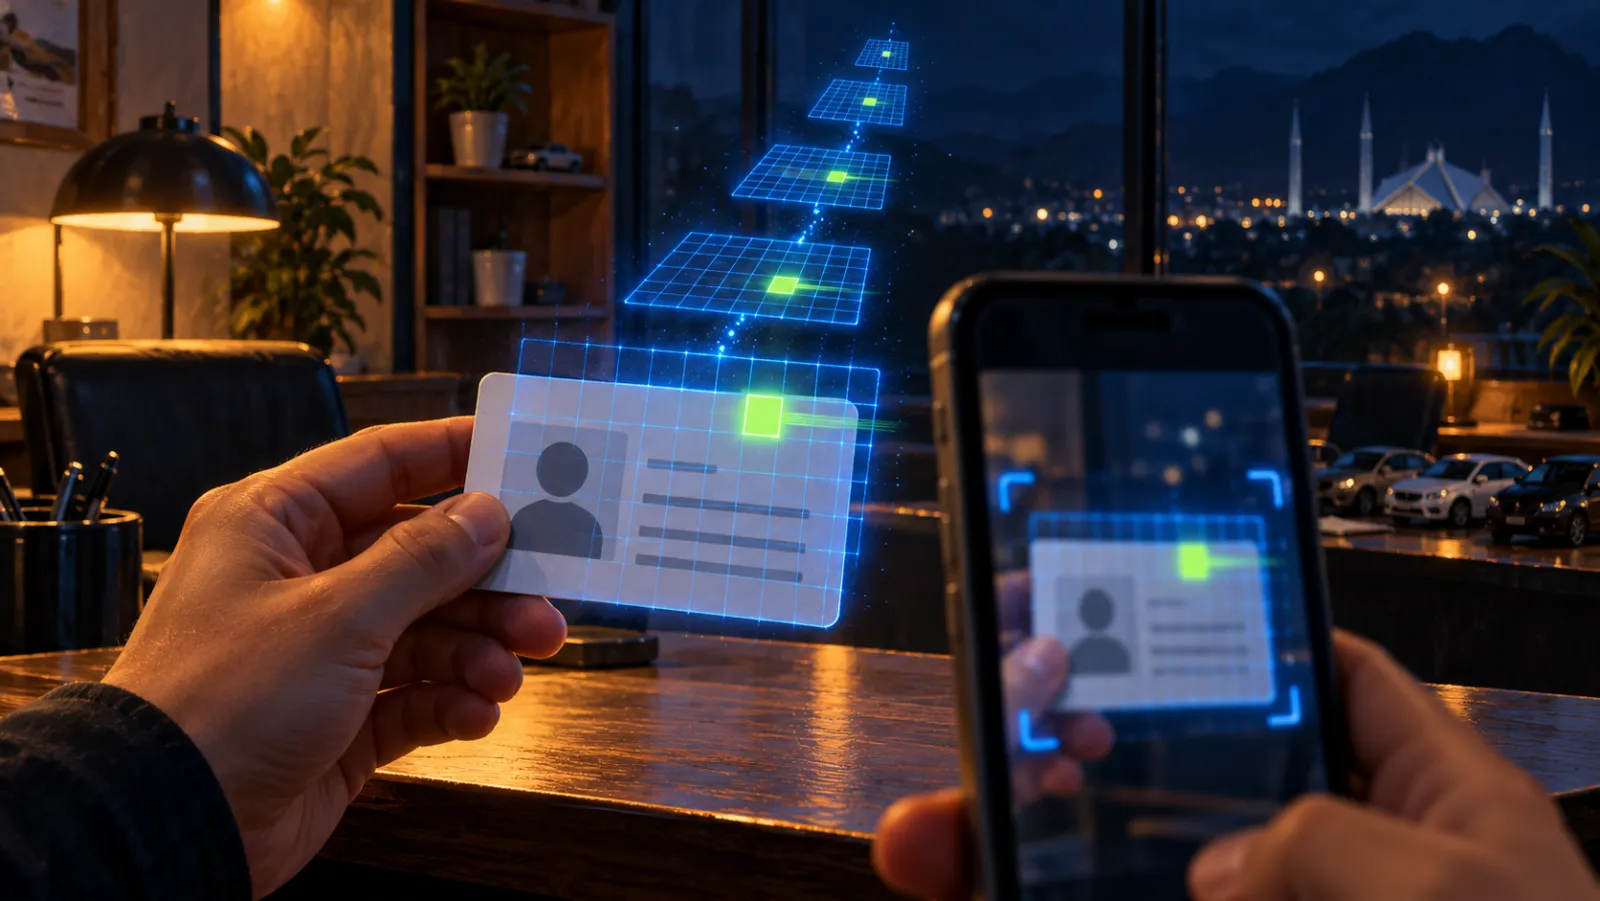
A customer walks into a rent-a-car office in Islamabad and hands over his CNIC. The manager photographs it with a phone. A second later, the name, CNIC number and date of birth appear in the booking form.
To you, the card obviously says "Muhammad Usman". To the computer, the photo is something very different: a grid of millions of numbers, each one saying how red, green and blue a tiny dot is. Nowhere in those numbers is the word "Usman".
So how does the machine get from dots to a name? Through a kind of network built specially for images: the convolutional neural network, or CNN.
A detective with a small magnifying glass
Imagine a detective who is only allowed to look at the card through a tiny magnifying glass, just a few pixels wide. She slides it across the whole card, row by row, looking for one specific thing, say a vertical line. Every time she finds one, she marks it on a fresh sheet of paper.
That small magnifying glass is a filter (also called a kernel), and sliding it across the image is a convolution. The sheet of marks she produces is a feature map: a picture of where vertical lines are.
Now give her a team. One detective looks for vertical lines, another for horizontal ones, another for curves, another for corners. Each produces their own map.
The key insight: the network learns what to look for on its own. Nobody programs "look for vertical lines". Training (Parts 1 and 2) adjusts the filters until they find whatever patterns help the most.
Layers build up meaning
The first layer's detectives find simple things: edges and lines.
The next layer looks at those maps and combines them. Two lines meeting at a corner. A curve joined to a straight line. Shapes start to appear.
A few layers deeper, the network is recognising whole characters: an "M", a "7", the dash in a CNIC number. Deeper still, it can recognise larger structures, like the position of the photo or the layout of the card.
Between layers, the network often pools, shrinking each map by keeping only the strongest signals in each small area. It's like the detective writing "there's a corner somewhere around here" instead of noting the exact pixel. This makes the network faster and less fussy about small shifts in position.
From letters to fields
Reading a document like a CNIC is called OCR (optical character recognition), and it usually happens in stages:
- Find the card in the photo and straighten it, even if it was taken at an angle.
- Find the text regions: where the name, number and dates are.
- Read the characters in each region, using networks like the one above.
- Make sense of it: check the CNIC number has the right format and put each value in the right field.
Why it works on messy phone photos
Real photos have glare, shadows, thumbs over corners and cards held at angles. Because the filters slide across the whole image, a CNN can spot an "M" wherever it appears. And by training on many varied examples (remember data augmentation from Part 3), it learns to ignore lighting and angle and focus on the shapes that matter.
The maths, briefly
A convolution slides a small filter over the image . Each value in the feature map is a weighted sum of the pixels under the filter:
Strictly, this is cross-correlation, which is what deep learning libraries compute, but everyone calls it convolution. For an input pixels wide, a filter of size , padding and stride , the feature map is this many pixels wide:
Max pooling then keeps only the largest value in each small window, for example each block.
What to remember
- To a computer, an image is a grid of numbers.
- CNNs slide small learned filters across the image to detect patterns.
- Early layers find edges; deeper layers combine them into shapes, characters and objects.
- OCR uses this to turn a photo of a document into structured data.
This is the kind of technology behind CNIC scanning in VibeRent, where a photo of the card fills in the customer's profile.
Images are grids of numbers by nature. Words are not. In Part 5, we see how AI turns words into numbers without losing their meaning.