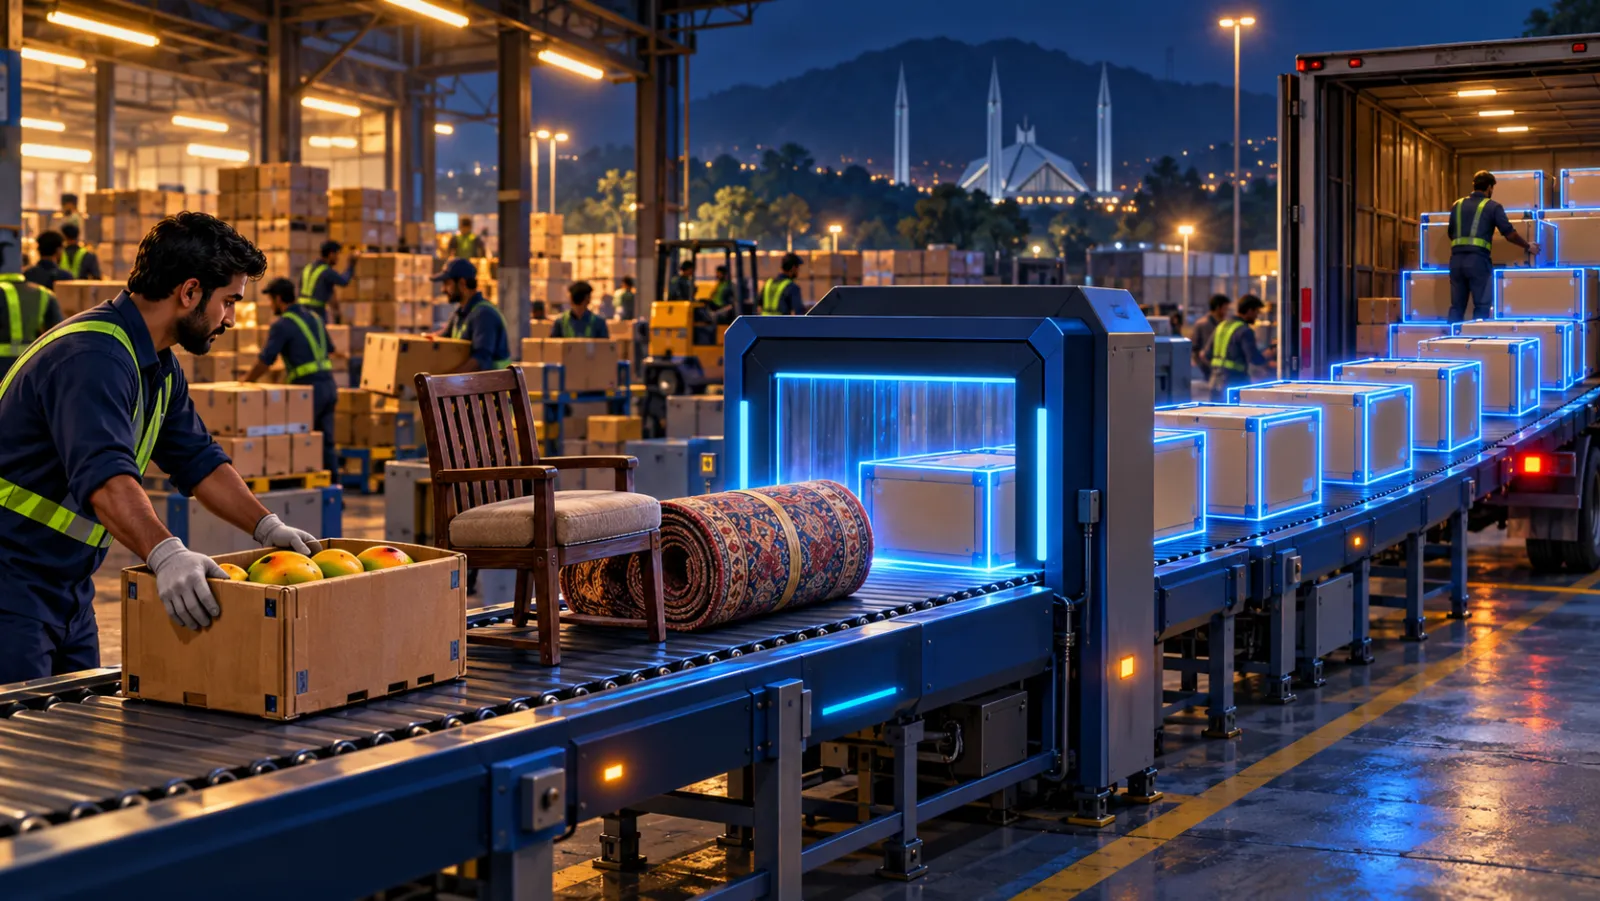
At the parcel counter of a courier office in Rawalpindi, Saleem has a problem. Customers bring boxes of every shape: a single envelope, a carton of mangoes, a set of chairs. His trucks only carry standard crates.
So Saleem has a rule. Common items that fit a crate go in whole. Big or unusual items get split into standard pieces. A dining table becomes "tabletop" + "legs" + "screws". Every piece gets a crate, every crate gets a number, and the trucks are packed with numbers.
AI models do the same thing with text. The standard pieces are called tokens.
Not letters, not words, but pieces
You might expect an AI to read one word at a time. But there are too many words: names, typos, new slang, technical terms, Roman Urdu. A dictionary of every possible word would be endless.
Reading one letter at a time is the other extreme. It works, but sentences become very long chains, and the model has to work much harder to see meaning.
So models use a middle path. Common words become one token. Rare words are split into common pieces:
- "the" → one token
- "running" → maybe "run" + "ning"
- "unbelievable" → maybe "un" + "believ" + "able"
- "VibePOS" → maybe "V" + "ibe" + "POS"
Every token has an ID number, and the model only ever sees those numbers. (Then, as Part 5 showed, each ID is turned into an embedding.)
How the pieces are chosen
A common method is byte-pair encoding (BPE). It starts with single characters, then looks through a huge amount of text and repeatedly glues together the pair of pieces that appears most often. "t" + "h" becomes "th". "th" + "e" becomes "the". It keeps going until it has a fixed-size vocabulary, often tens of thousands to a couple of hundred thousand tokens.
The result is a vocabulary shaped by the text it was built from. That has consequences.
Why tokens matter in real life
1. Pricing. AI services usually charge per token, for both what you send and what you get back. In English, a token is very roughly three quarters of a word on average.
2. Limits. Every model has a context window, the maximum number of tokens it can consider at once. A long contract, a full chat history and a big knowledge base all compete for that space.
3. Languages are not equal. If the vocabulary was built mostly from English text, English words get efficient single tokens, while Urdu script, Roman Urdu or Arabic often get split into many more small pieces. The same sentence can cost more tokens, and use more of the context window, in Urdu than in English.
The maths, briefly
At each step, BPE finds the adjacent pair of symbols that appears most often in the training text and merges it into one new symbol:
It repeats until the vocabulary reaches its target size . Sennrich, Haddow and Birch brought this method to language models in 2016, borrowing it from an older data-compression technique.
What to remember
- AI models read tokens: common words whole, rare words in pieces.
- Each token is a number, which then becomes an embedding.
- Tokens decide cost and how much text fits in the model's memory at once.
- Languages that were rare in the training text usually need more tokens.
Now we have numbers for every piece of text. In Part 7, we meet the idea that changed AI: letting every token listen to every other token.