Read this sentence:
Ali put the cake in the fridge because it was too warm.
What does "it" mean? The cake. Now change one word:
Ali put the cake in the fridge because it was too full.
Now "it" means the fridge. You worked that out instantly, because you looked at the whole sentence and noticed which words mattered. For decades, computers could not do this well. In 2017, a paper from Google called "Attention Is All You Need" changed that. It introduced the Transformer, the design behind almost every modern AI language model.
The old way: passing a message down the line
Before Transformers, language models (called RNNs) read one word at a time, left to right, carrying a running summary along, like the old game where a message is whispered from person to person down a line.
By the time the summary reaches the end of a long paragraph, the early details have faded. And because each step waits for the previous one, it is slow: you can't whisper to the tenth person until the ninth has heard.
The new way: a family meeting
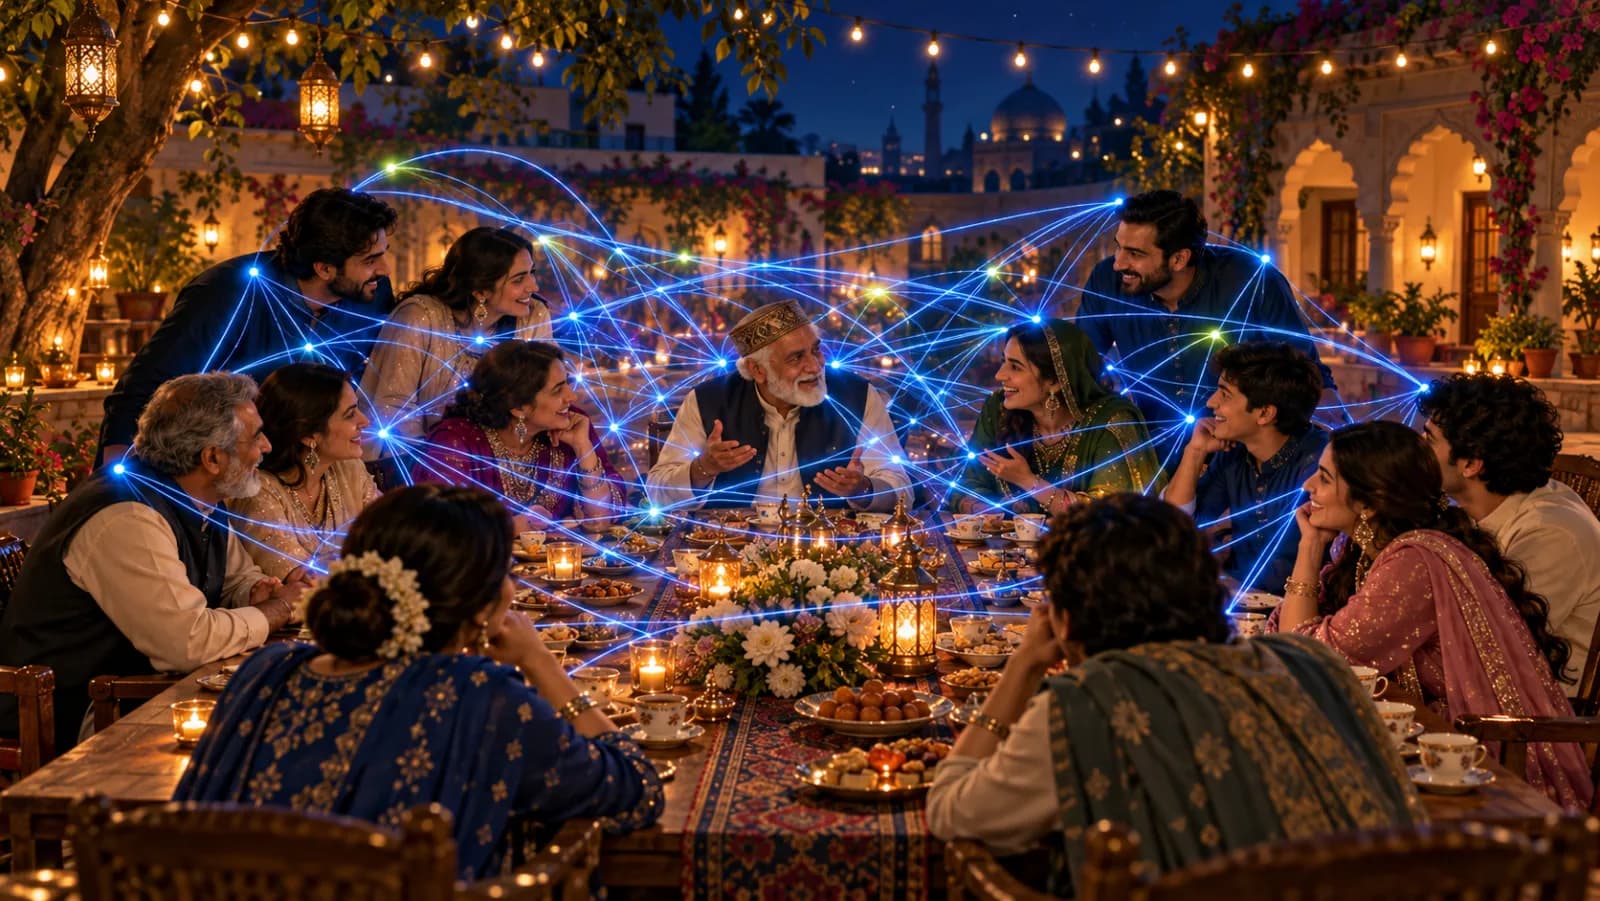
Now imagine a family meeting about a wedding, where everyone sits around one big table. Each person can hear everyone else at the same time, and decides for themselves whose words matter most to them.
The aunt in charge of food listens closely to the caterer and the guest count. The cousin handling transport listens to the venue and the date. Nobody waits in line.
In a Transformer, every word is a person at that table. This is called self-attention.
Questions, labels and answers
How does each word decide who to listen to? Every word produces three things:
- A query: what am I looking for? ("it" asks: which noun am I referring to?)
- A key: what do I offer? ("cake" says: I'm a thing that can be warm.)
- A value: the information I'll share if you listen to me.
Each word compares its query with every other word's key. Strong matches get more attention. Then it collects a mix of their values, weighted by that attention. After this step, "it" literally carries information from "cake" (or from "fridge"), depending on the sentence.
Remembering who sat where
Because everyone hears everyone at once, word order could get lost. "Ali paid Sara" and "Sara paid Ali" use the same words. So Transformers add positional information to each word's embedding, a kind of seat number, so the model knows the order.
Stack the meetings
One meeting isn't enough. A Transformer stacks many layers of these attention meetings, each followed by a small neural network (Part 1) that processes what was gathered. Early layers sort out grammar and nearby words. Later layers handle meaning, facts and reasoning across the whole text.
Why it changed everything
- Long-range understanding. A word on page five can directly attend to a word on page one.
- Speed. All words are processed in parallel, which suits modern graphics chips (GPUs) perfectly. That made it possible to train on enormous amounts of text.
- It's general. The same design now works for text, images, audio, code and more.
The maths, briefly
Stack every token's query, key and value into matrices , and . Attention is then one line:
compares every query with every key. Dividing by , the square root of the key size, keeps the scores in a sensible range. Softmax turns each row of scores into weights that add up to 1, and those weights mix the values.
The original paper adds position information using waves of different frequencies, for position and dimension of a -dimensional embedding:
Multi-head attention runs of these attention calculations in parallel on smaller slices of each vector, then joins the results.
What to remember
- A Transformer lets every token look at every other token at once: self-attention.
- Each token uses a query, key and value to decide who to listen to and what to take.
- Multiple heads and many stacked layers build deep understanding.
- Parallel processing made it possible to train models on huge amounts of text.
So what happens when you train a giant Transformer on most of the internet and ask it to predict the next word? That's Part 8.