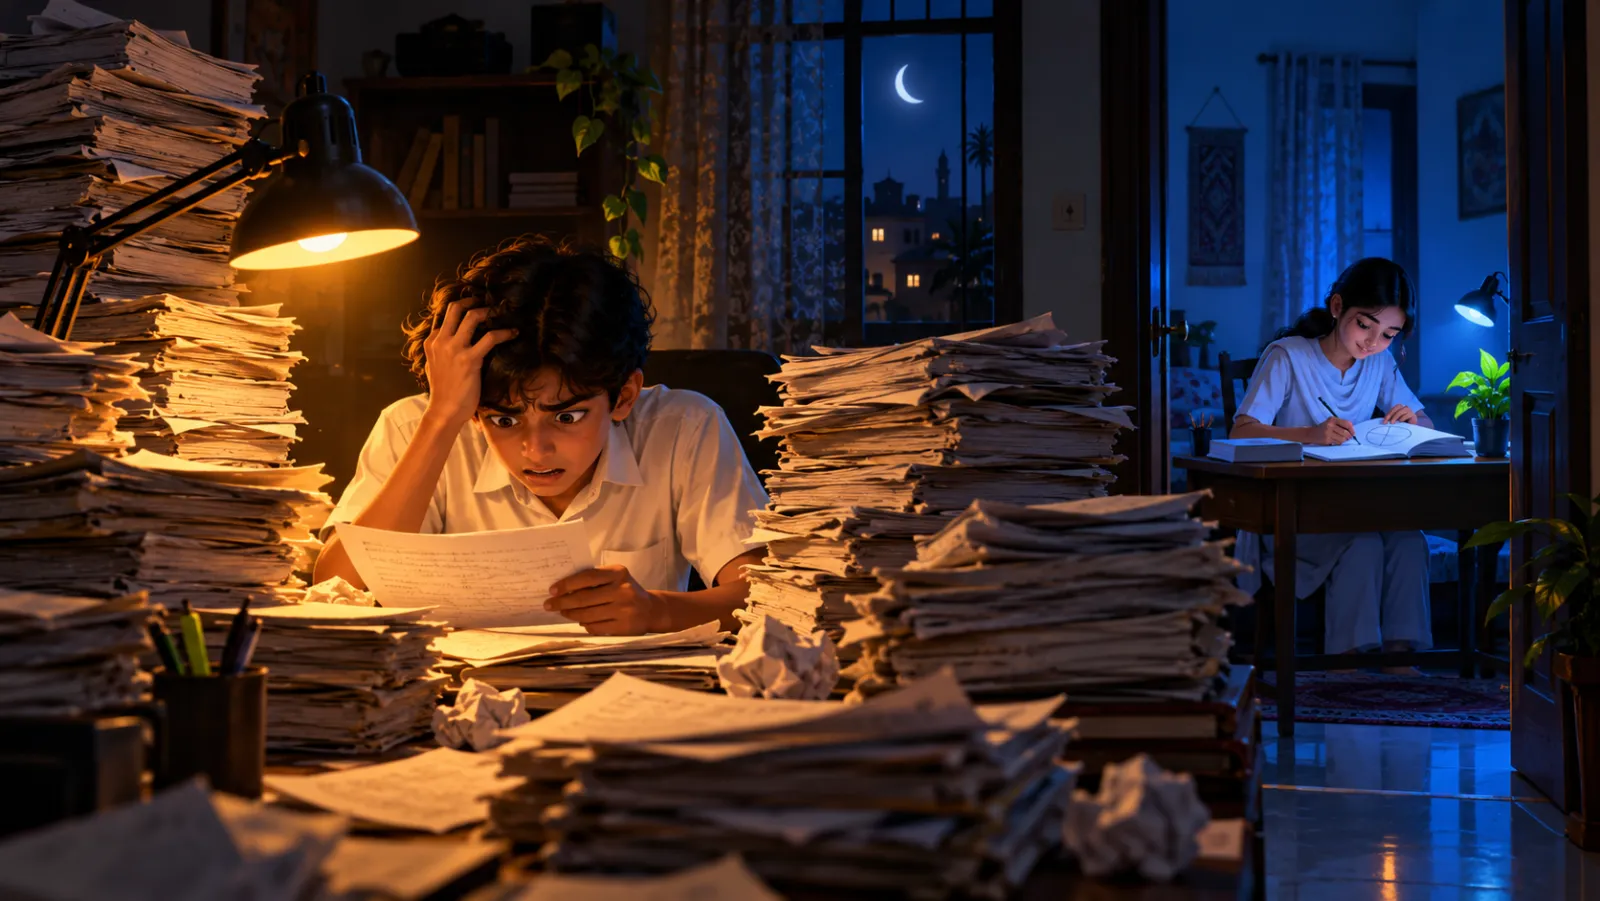
Every school has an Ahmed. Two months before the matric board exams, he buys every past paper for the last ten years and learns them by heart. Not the concepts. The exact answers.
In the practice tests he is unbeatable. Question 4(b) from 2019? He writes the answer before the teacher finishes reading it.
Then the real exam arrives. The board has changed the numbers in the physics questions and reworded the chemistry ones. Ahmed freezes. He knows hundreds of answers and understands none of them.
His classmate Hira scored lower in the practice tests. But she had spent her time understanding why the answers worked. In the board exam, she does far better.
Ahmed overfitted. Hira generalised. This is the difference every machine learning engineer worries about.
What overfitting looks like in a model
A model learns from training data, the examples we show it. If it is powerful enough and we train long enough, it can start memorising those exact examples, including their noise and accidents, instead of learning the real pattern.
The result: near-perfect scores on the training data and poor results on anything new. Like Ahmed, it has learned the past papers, not the subject.
The opposite problem is underfitting: a model too simple to learn even the training data well, like a student who never studied at all.
The fix starts with a test it has never seen
The most important habit in machine learning is to hold back some data the model never trains on.
- Training set: the past papers you study from.
- Validation set: mock exams you use to check progress and make decisions during studying.
- Test set: the real board exam, opened only once at the very end.
If the training score keeps going up while the validation score starts going down, the model has started memorising. That is the moment to stop.
How engineers stop memorising
- Early stopping. Stop training when validation results stop improving, even if training results still could.
- More and more varied data. It is hard to memorise a million different questions. More variety pushes the model towards real understanding.
- Data augmentation. For images, show the same photo slightly rotated, darker or cropped. A CNIC photo taken at an angle is still the same CNIC.
- Regularisation. Penalise the model for leaning too heavily on any single detail, so it keeps its "rules" simple.
- Dropout. During training, randomly switch off some neurons each time, so no single neuron can carry a memorised answer. It is like a study group where a random member is absent each day, so everyone has to actually understand the material.
The maths, briefly
L2 regularisation, also called weight decay, adds a penalty for large weights to the loss, with setting how strong the penalty is:
Dropout (Srivastava et al., 2014) switches off each neuron with probability during training, so the network cannot rely on any single one. At prediction time, all neurons are used.
What to remember
- Overfitting means memorising the training examples instead of learning the pattern.
- You only catch it by testing on data the model has never seen.
- More varied data, early stopping, regularisation and dropout all push models towards understanding.
Hira learned the concepts. In Part 4 we look at how a model learns the concepts of a picture: edges, shapes and, eventually, the letters on an ID card.