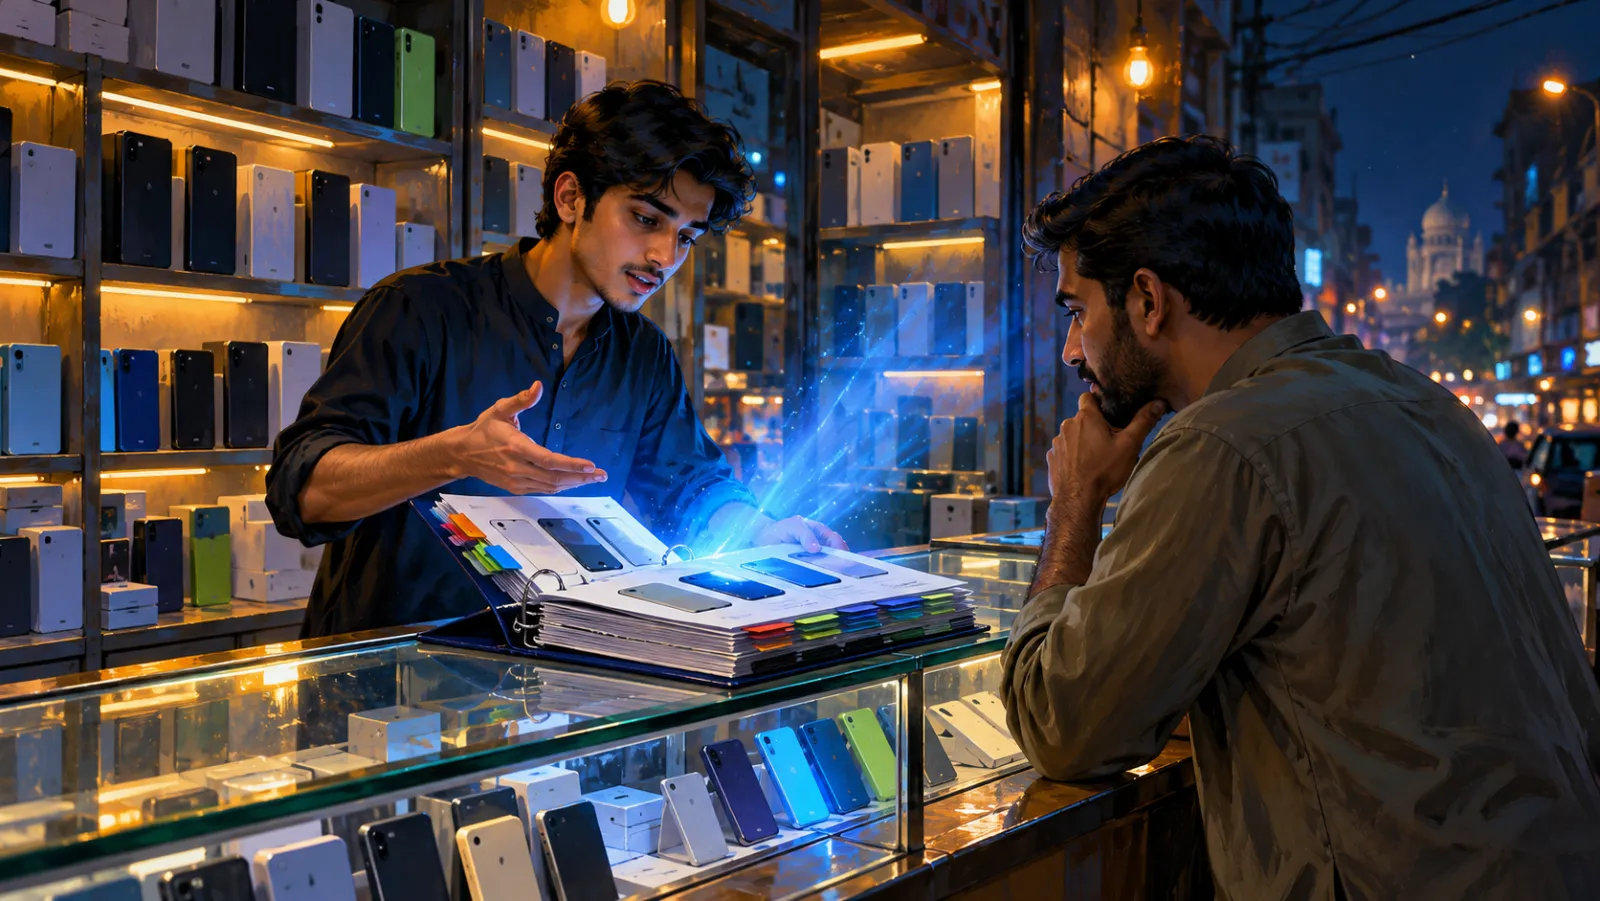
Zain joins a mobile phone shop in Saddar as a sales assistant. He is smart, polite and good with customers. But it's his first day, and he doesn't know the shop's prices, warranty rules or which models are in stock.
The owner could make him memorise everything. That would take weeks, and prices change every few days anyway.
Instead, the owner gives Zain a thick binder: the price list, warranty policy, stock sheet and answers to common questions, all with tabs. When a customer asks something, Zain flips to the right page, reads it, and answers in his own friendly words.
Zain is no longer guessing. He's taking an open-book exam. In AI, this is called retrieval-augmented generation, or RAG.
The problem RAG solves
In Part 8 we met the confident uncle: an LLM that writes fluent answers but can make things up. It is especially weak on things it never saw during training:
- your prices, products and policies
- anything that changed after it was trained
- private documents like contracts, patient records or internal SOPs
Retraining a giant model every time your price list changes is impractical. RAG is the shortcut: keep the model as it is, and hand it the right pages at the moment it answers.
How the binder is built
Before any customer arrives, the documents are prepared:
- Split each document into small passages, a few paragraphs each. These are the binder's pages.
- Embed each passage, turning it into coordinates on the meaning map from Part 5.
- Store those coordinates in a searchable index, often called a vector database. These are the tabs.
What happens when a question arrives
Customer: "Do you give a warranty on used iPhones?"
- Retrieve. The question is embedded too, and the system finds the passages closest to it on the meaning map. It finds the warranty policy page even though the policy might say "pre-owned devices" rather than "used iPhones".
- Augment. Those passages are placed into the model's prompt with an instruction like: Answer using only the information below. If the answer isn't there, say so.
- Generate. The LLM writes a natural, friendly reply based on those pages.
That's the whole idea: retrieve, then generate.
Why businesses love it
- Accuracy. Answers come from your real documents, not the model's memory.
- Always current. Update the price list and the next answer uses it. No retraining.
- Traceable. The system can show which document an answer came from, so staff can check it.
- Private. Your documents stay in your own store and are shown to the model only when needed.
The idea comes from a 2020 research paper by Patrick Lewis and colleagues, and it is now one of the most common ways businesses put LLMs to work.
The maths, briefly
The question and every passage are turned into vectors by an embedding model , and the passages with the highest similarity are retrieved:
The original RAG paper treats the retrieved passage as a hidden choice and combines the answers it supports:
Most business systems use a simpler version: put the top passages into the prompt and let the LLM write the answer.
What to remember
- RAG lets an AI answer from your own documents, like an open-book exam.
- Documents are split, embedded and stored; questions retrieve the closest passages.
- The LLM writes the answer using those passages, not its memory.
- It keeps answers accurate and current without retraining the model.
This is the same idea behind AI agents that answer customers from a business's own knowledge base, like the ones in Business OS and VibeCall.
In the final part, we leave words behind and look at how AI creates images, starting from pure noise.