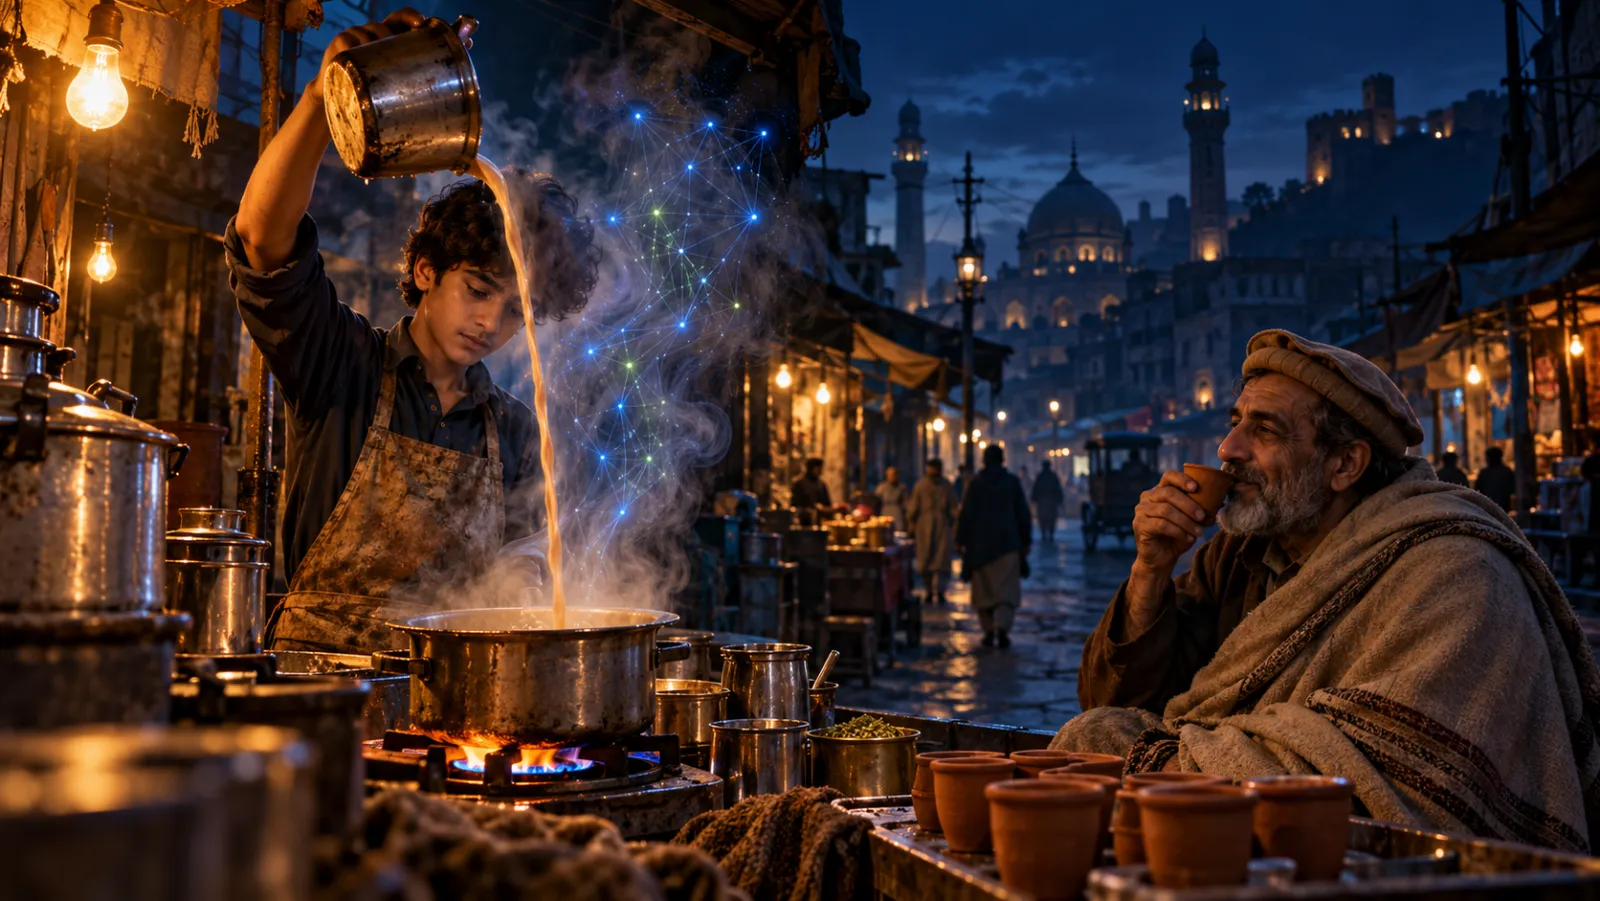
Bilal is fourteen and has just started at Ustad Rafiq's chai stall near the Raja Bazaar. On his first morning, the Ustad hands him a pan and says one thing: "Make it taste like mine."
Bilal has four things he can change. How much tea leaf. How much sugar. How much milk. How long it boils. He has no recipe. He has only the Ustad, who tastes every cup and says how far off it is.
The first cup is terrible. "Too sweet, too weak," says the Ustad. Bilal uses a little less sugar and a little more tea. The second cup is better, but now it's bitter. He adjusts again. By the end of the week, his cup is almost exactly like the Ustad's, and nobody ever wrote the recipe down.
Bilal just did what a neural network does.
The knobs are called weights
A neural network is a machine with a very large number of knobs. In Bilal's case there are four: tea, sugar, milk and boiling time. In a modern AI model there are billions.
Each knob is called a weight. A weight decides how much one input matters to the result. If the "sugar" weight is high, sugar has a big effect on the taste. If it is close to zero, sugar hardly matters.
At the start, the weights are set at random. That is why Bilal's first cup, and a new network's first answer, is nonsense.
Neurons: small judges in a row
A single neuron takes several inputs, multiplies each one by its weight, adds them up and decides how strongly to "fire". You can imagine it as a small judge who looks at a few clues and gives one score.
One judge is not very smart. So networks line them up in layers:
- The first layer looks at the raw ingredients: amounts of tea, sugar, milk, time.
- The middle layers combine those into ideas: "strong", "creamy", "too sweet".
- The last layer gives the final answer: how close this cup is to the Ustad's.
Stacking many layers is what the word deep in "deep learning" means.
The taste test is the loss
Every time the Ustad tastes a cup, he gives a number for how wrong it is. In machine learning this number is called the loss. A loss of zero means a perfect cup.
The whole goal of training is simple to say: change the knobs until the loss is as small as possible.
Blame flows backwards
Here is the clever part. When the Ustad says "too bitter", Bilal does not change everything at random. He thinks backwards: bitterness came mostly from boiling too long and using too much tea leaf, a little from too little milk. So he changes those knobs most.
Neural networks do the same thing with an algorithm called backpropagation, made popular in a 1986 paper by Rumelhart, Hinton and Williams. After each mistake, the error is passed backwards through the layers, and every weight gets its share of the blame. Weights that caused more of the error change more.
How big each nudge should be is its own story. That is Part 2, about walking down a hill in the fog.
Why examples beat rules
Nobody told Bilal "use 2.5 teaspoons of sugar". He learned it from hundreds of tastings. This is the big shift that neural networks brought: instead of writing the rules, we show examples and let the machine find the rules itself.
That is why a network can learn to recognise a face, read a CNIC or understand a WhatsApp message. Those are all problems where writing the rules by hand is almost impossible, but collecting examples is easy.
The maths, briefly
One neuron multiplies each input by its weight , adds a bias , and passes the total through an activation function , a simple bend such as ReLU, :
A common loss is the mean squared error between the network's guesses and the right answers over examples:
Backpropagation uses the chain rule from calculus to work out for every weight: how much the loss changes when that one weight moves a little.
What to remember
- A neural network is layers of simple units (neurons) connected by adjustable numbers (weights).
- Training means showing examples, measuring the mistake (loss) and adjusting the weights to reduce it.
- Backpropagation decides which weights to blame for each mistake.
- Given enough examples, the network finds patterns nobody wrote down.
Next, we look at how Bilal decides how much to change each knob, and why taking steps that are too big is as bad as taking steps that are too small.